Introducing toks
Actual Computer is pleased to announce its first public software release. We're starting small and serious, with toks.
Actual's toks is the best tokenizer on earth. It's built for production-grade workloads. It's faster than anything else, in every condition, for every model. It's tiny, embeddable, and easy to upgrade.
At Actual we spend a lot of time counting tokens, so it only made sense for us to make a better tokenizer. We designed toks for the quadrillion-token era. Where token production turns into the most dominant workload on earth.
Give it any type of tokenizer info that Hugging Face tokenizers would take and it'll run and return the exact same ids you'd get from Hugging Face tokenizers or tiktoken, but 100x faster. We wrote toks as a small library of asm hot paths, with some C glue to keep it together and some Python for easy use. We believe we're at the dawn of a new era, where inhuman code becomes the de facto standard. That's why over toks's lifetime, more and more of it will be written in explicit and perfectly optimized asm.
It's Not Close
We pushed toks to only be bounded by the physical limits of the hardware it runs on. Like all software we develop at Actual, we believe the only limit to your speed should be in the silicon. To accomplish that here, toks has most of its computations run in pure assembly, allowing us to reach speeds that are orders of magnitude faster than other tokenizers.
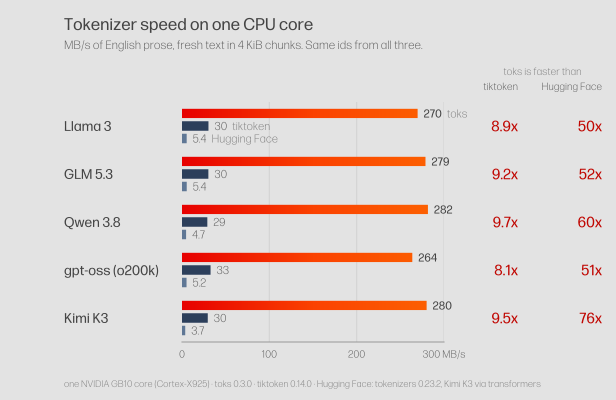
On one CPU core, with fresh text:
- 13x to 151x faster than Hugging Face tokenizers, in every cell of the speed table.
- Faster than tiktoken in every cell tiktoken can run: 195 of 195.
- Faster than gigatoken in 252 of 255 cells.
- Llama 3 on English prose, one GB10 core: toks 269.8 MB/s, tiktoken 30.3, Hugging Face 5.36.
- Kimi K3 on code: toks 474.3 MB/s, tiktoken 26.2, Hugging Face 3.84. That's 124x.
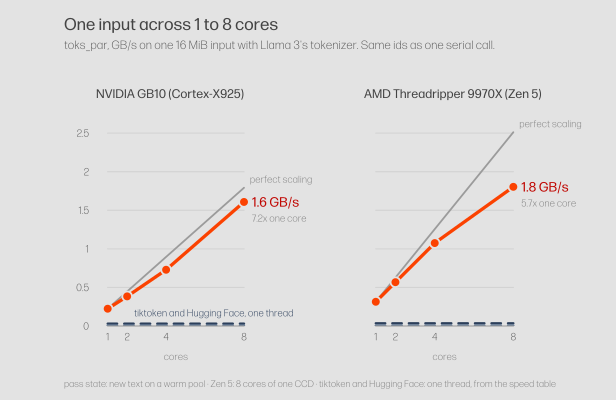
On a few cores, toks_par encodes one 16 MiB input at 1.6 GB/s on 8 GB10 cores and 1.8 GB/s on 8 Zen 5 cores, with exactly the ids of one serial call.
Perfect Parity
- Same ids as Hugging Face tokenizers 0.23.2, which defines the right answer.
- Every release target is checked against it on every CPU tier, over millions of cases per model, with 0 diffs.
- A tokenizer toks can't reproduce exactly is refused at load, with the missing feature named. You never get quietly different ids.
- There's no compat mode that trades exactness for speed. The exact mode is the fast mode.
- toks loads 99%+ of the top Hugging Face models by downloads.
Our First Public Release
- Source-available under the Business Source License 1.1.
- Free for any organization that processes fewer than one quadrillion (10^15) tokens a year. That's about 32 million tokens a second, around the clock. Production use, modifying it, vendoring it and shipping it inside your product are all covered.
- Every version becomes Apache 2.0 four years after its first public release. For toks 0.3.0 that's October 5, 2030.
- At or above the line, an inexpensive commercial license from Actual Computer.
Get It
https://github.com/actual-computer/toks
Python wheels for CPython 3.10 to 3.14 and C bundles for linux arm64, linux x86-64 and macOS arm64 are attached to the v0.3.0 release.
import toks

tok = toks.Tokenizer.from_file("path/to/tokenizer.json")
ids = tok.encode("Hello world")  # == Hugging Face's tok.encode("Hello world").ids